ITSM knowledge management for an AI-first service desk
Learn how ITSM knowledge management changes when AI agents become the primary users of your documentation, including what makes knowledge agent-ready and when to use a runbook instead.

Most IT teams already have useful support knowledge. The problem is that it rarely lives in one clean knowledge base. Answers may be scattered across Confluence, Google Drive, Slack, old tickets, or people’s heads, and employees often ask IT instead of searching for them themselves.
Keeping that knowledge current is difficult when documentation competes with support work. Updates get postponed, and articles gradually fall out of date.
Today, that matters more than ever. AI agents can use your existing documentation while resolving employee requests, pulling in relevant information and applying it to the employee’s problem. That means the quality of your knowledge can directly affect whether a routine request is resolved automatically or escalated to IT.
This guide explains what changes when an AI agent starts using your ITSM knowledge, how to make help articles easier for an agent to interpret and apply, and when a process belongs in a runbook instead. We’ll also show you how to identify which knowledge articles to improve first.
TL;DR
- ITSM knowledge management captures and maintains the information used to resolve internal support requests. With AI, that knowledge can feed directly into automated resolution.
- A human can fill in missing context. An AI agent needs conditions, named systems, expected outcomes, and current instructions to be stated clearly.
- Don’t start by rewriting the whole knowledge base. Prioritize articles tied to high-volume requests that repeatedly escalate to IT.
- Knowledge articles help answer common questions, while runbooks define the workflows an AI agent follows to resolve tickets.
- Use auto-solve rate to track whether improving your knowledge helps more repeatable requests get resolved without human involvement.
Why ITSM knowledge bases go stale
Traditional ITSM knowledge management is built around a sensible cycle: capture what the team learns, turn it into reusable documentation, make that information accessible, and keep it up to date.
As we mentioned above, the difficult part is keeping that cycle running while the service desk is busy. Common problems include:
- Support requests take priority over documentation. Writing up a resolution is easy to postpone when there’s a backlog waiting. The immediate ticket gets closed, but the fix never becomes reusable knowledge. When that happens repeatedly, the knowledge base stops reflecting how the team actually solves common issues.
- Knowledge is spread across different sources. Knowledge can be spread across Confluence, Notion, Google Drive, and Slack threads, which makes it difficult to know which source has the most current answer. A new fix might be shared in Slack while an older version remains in the knowledge base.
- Stale information remains available to the AI agent. Outdated articles aren’t the only source of stale knowledge. An AI agent may also retrieve information from old tickets, Slack threads, archived pages, or duplicate copies that are still included in its index. If one of those sources conflicts with the current documentation, the agent can still surface the wrong answer.
- Articles don’t have clear ownership. An article can be accurate when it’s published and still become outdated as systems, tools, or internal processes change. Without a clear owner or a trigger to review the article when those changes happen, outdated instructions can stay in place.
What changes when an AI agent reads the knowledge base
Until recently, IT knowledge bases were written primarily for people. Even when the documentation is incomplete, a person can often fill in the gaps using experience and context.
We’re now shifting toward agentic ITSM, where AI agents use provided context and connected systems to resolve employee requests.
An AI agent working on a request retrieves relevant knowledge, combines it with the context of the request, and uses that information to determine how to respond.
That also means deciding which knowledge the agent should be able to retrieve. Some teams mark approved pages as ‘AI-ready’ or verified so the agent only uses content that is current and appropriate for its audience.
If an article leaves out an important condition or assumes the reader already knows which system or process applies, the agent may not have enough information to resolve the request.
That raises the standard for ITSM knowledge management. Articles need to contain enough explicit information for an agent to use them reliably. When they don’t, requests that could have been handled through AI ticketing automation may instead be escalated to IT.
What makes a knowledge article machine-actionable
A knowledge base article can be accurate and perfectly understandable to an experienced IT employee while still leaving too much unstated for an AI agent.
A useful test is whether the article gives the agent enough information to know which instructions apply and what outcome to look for.
Below, we’ll show you how to make those details explicit so an AI agent doesn’t have to fill in missing context.
Explicit conditions
An AI agent needs to know exactly when each instruction applies so it can choose the right next step.
For example, an article on how to troubleshoot VPN issues might say, ‘Reconnect to the VPN and try again.’ A human may understand that this step only applies if the employee is disconnected, but an AI agent shouldn’t have to infer that.
Instead, spell out the different situations:
- If the employee is disconnected from the VPN: reconnect and try the application again.
- If the employee is already connected: check whether the VPN client shows an authentication or connection error.
Also, watch for phrases such as ‘usually,’ ‘where appropriate,’ or ‘if needed.’ They can hide conditions that should be stated explicitly.
Named systems
When an instruction depends on a specific system, name it directly.
Compare ‘Reset the employee’s password in the admin tool’ with ‘Reset the employee’s password in Okta.’ The second instruction names the exact system involved.
If the article is used as part of an automated workflow, naming the system helps the AI agent match the instruction to the correct integration or tool.
The same applies to people. If a specific role needs to take action, name that role rather than referring vaguely to ‘the owner.’
Resolvable steps
A step should leave the agent with a clear result it can check. So, instead of: ‘Confirm that the settings are correct.’
Write: ‘In the Google Workspace Admin console, confirm that the employee’s account status shows Active. If it shows Suspended, escalate the request to IT.’
Current access path
A system may have been replaced, an approval workflow may have changed, or the way a task is completed may no longer match the article. In that case, the agent can follow the documentation correctly and still fail to resolve the request.
Update articles when the underlying tool or process changes. For example, if you replace your identity provider or change an access approval workflow, update the related documentation as part of that change.
Where knowledge articles end and runbooks begin
Making your knowledge articles easier for an AI agent to use still leaves an important question: when should something be documented as an article, and when should the process be handled by a runbook?
The simplest distinction is:
- Knowledge articles provide information. Employees can read them to understand a standard process or get an answer to a common question. An AI agent can also retrieve that information to answer questions and understand organizational context.
- Runbooks define workflows. They tell the AI agent how to handle a particular type of request, including how to interact with the employee, which actions to take, and any approvals or steps that need to happen before the ticket can be resolved.
For example, if an employee asks how to install the Cloudflare client on macOS, the AI agent can retrieve the relevant article and use those instructions to answer the question.
A FileVault recovery request is different. Resolving the ticket requires a defined workflow: verify the employee’s identity, retrieve the recovery key from a mobile device management (MDM) system, and securely send it to the employee. That process is better suited to a runbook.
Not every request needs an article or a custom runbook. Standard access requests, for example, may be handled through access rules and an application catalog, where predefined logic determines how the request should be approved and fulfilled.
That doesn’t mean every repeatable request needs a runbook either. For the long tail of common questions, a knowledge article is usually a more scalable way to give employees and the AI agent the information they need.
Knowledge articles and runbooks can also work together as part of a wider IT support automation workflow. A workflow might require the AI agent to use a specific piece of approved knowledge before continuing.
For example, Risotto can restrict a runbook to specific knowledge articles, so the agent uses the approved source for that workflow. Before granting AWS access, a runbook could ask the employee to review a relevant Confluence article and check that the reason for the request meets the required guidelines before continuing.
Not every piece of knowledge needs to live in your internal knowledge base either. If the information already exists in a vendor’s documentation, an AI workflow may be able to retrieve that source when it needs it.
Risotto, for example, can use a tool within a runbook to search Brex’s official support site in real time when an employee asks for help using Brex, so the IT team doesn’t have to maintain a duplicate set of instructions internally.
Which knowledge articles should you improve first?
Once you’ve separated the requests that need knowledge articles from those better handled by runbooks, the next step is deciding which articles to improve first.
Don’t start by reviewing your knowledge base alphabetically. Start with the repeatable request types that are creating the most work for your IT team.
Look at which of those requests the AI agent still escalates and why. If the agent is missing information it needs to answer the request, improve or create the relevant knowledge article. If resolving the request requires the agent to follow a workflow and take action, consider whether it belongs in a runbook instead.
Use the data your service desk already generates to spot the biggest knowledge gaps. Look for high-volume request types that still escalate, searches that return no useful answer, and articles that are retrieved but don’t help resolve the request. Those patterns show you where better knowledge is most likely to reduce manual work. This reflects the signals customers are already using to identify knowledge gaps.
Not every article is worth updating. If an article duplicates a newer source or documents a process that no longer exists, retire it rather than rewriting it, and remove it from the agent’s index so it can’t continue to surface.
As you make changes, track auto-solve rate for these request types. Alongside your other ITSM metrics, this is a clear way to see whether improving an article actually helps the AI agent resolve more requests without human involvement.
Knowledge quality is now an auto-solve lever
Once an AI agent is using your knowledge base to resolve employee requests, article quality becomes part of how effectively your service desk operates. Clear, current knowledge gives the AI agent a stronger foundation for resolving requests without needing to hand them back to IT.
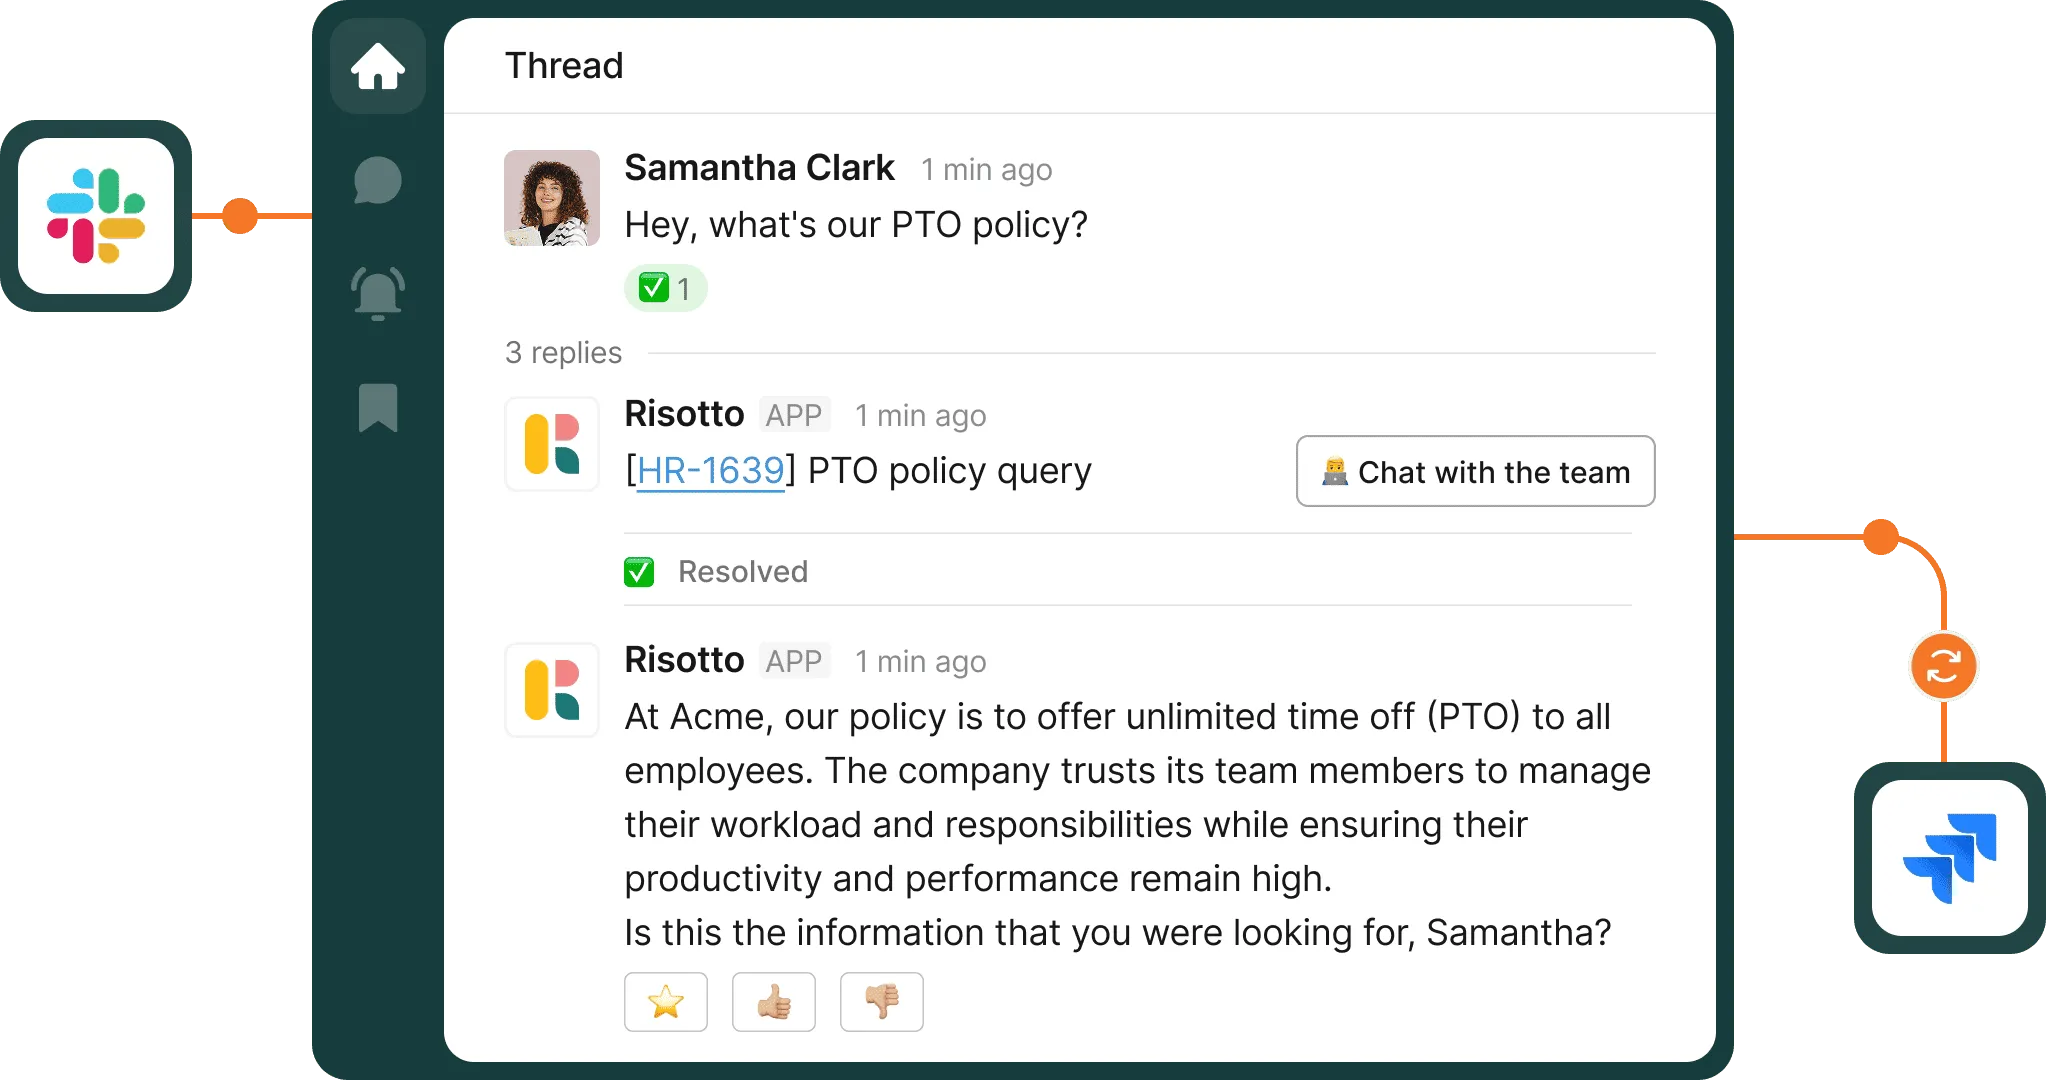
For that knowledge to be useful, the AI agent also needs to be able to access and reuse it easily. Risotto can use knowledge your team already has across tools such as Confluence, Notion, Google Drive, and Slack.
It indexes those sources so the AI agent can retrieve relevant information when answering employee requests. Risotto can also turn useful information from resolved tickets into new knowledge articles, so that those answers are available the next time a similar request comes in.
Frequently asked questions
ITSM knowledge management is the process of capturing, maintaining, and applying information used to deliver IT services and resolve support requests. In an AI-first service desk, that knowledge also supports automated resolution. It becomes an input for AI agents, by helping them find the information they need to answer requests.
Better knowledge gives an AI agent clearer information to work from when resolving employee requests. When articles are current, specific, and easy for the agent to interpret, fewer repeatable requests need to be escalated to IT.
Liked the article? Share on:
On this page
See how Risotto combines your existing knowledge with automated runbooks to resolve employee requests automatically.


See more recent articles
Want faster solutions and happier employees?
Access that's easy to ask for and impossible to get wrong.
Ensure Legal never answers another "do we need an NDA for this?"
Every policy question is stealing time from the work Finance was hired to do.
Turn Slack requests into action items instead of engineering interruptions.
The biggest deal risk might be an unanswered internal question.
Run a united support system that your employees can depend on.
Build the automations you’ve been planning on for months.
The bottleneck isn't your team. It's the groundwork before they can actually help.
Get support data that your team can talk to.
Jump on a call to understand:
Risotto handles repetitive support requests across tools and teams, so IT gets back to solving real problems, not rerunning the same ones.

See what makes the Iru integration a 10/10 for our clients.